System diagnostics
Node.js process metrics and MongoDB statistics for the Checkmate server itself.
Overview
The Diagnostics tab reports Node.js process metrics from the Checkmate server itself, not from anything you're monitoring. It's for checking the health of the Checkmate instance. Admin or Superadmin role is required.
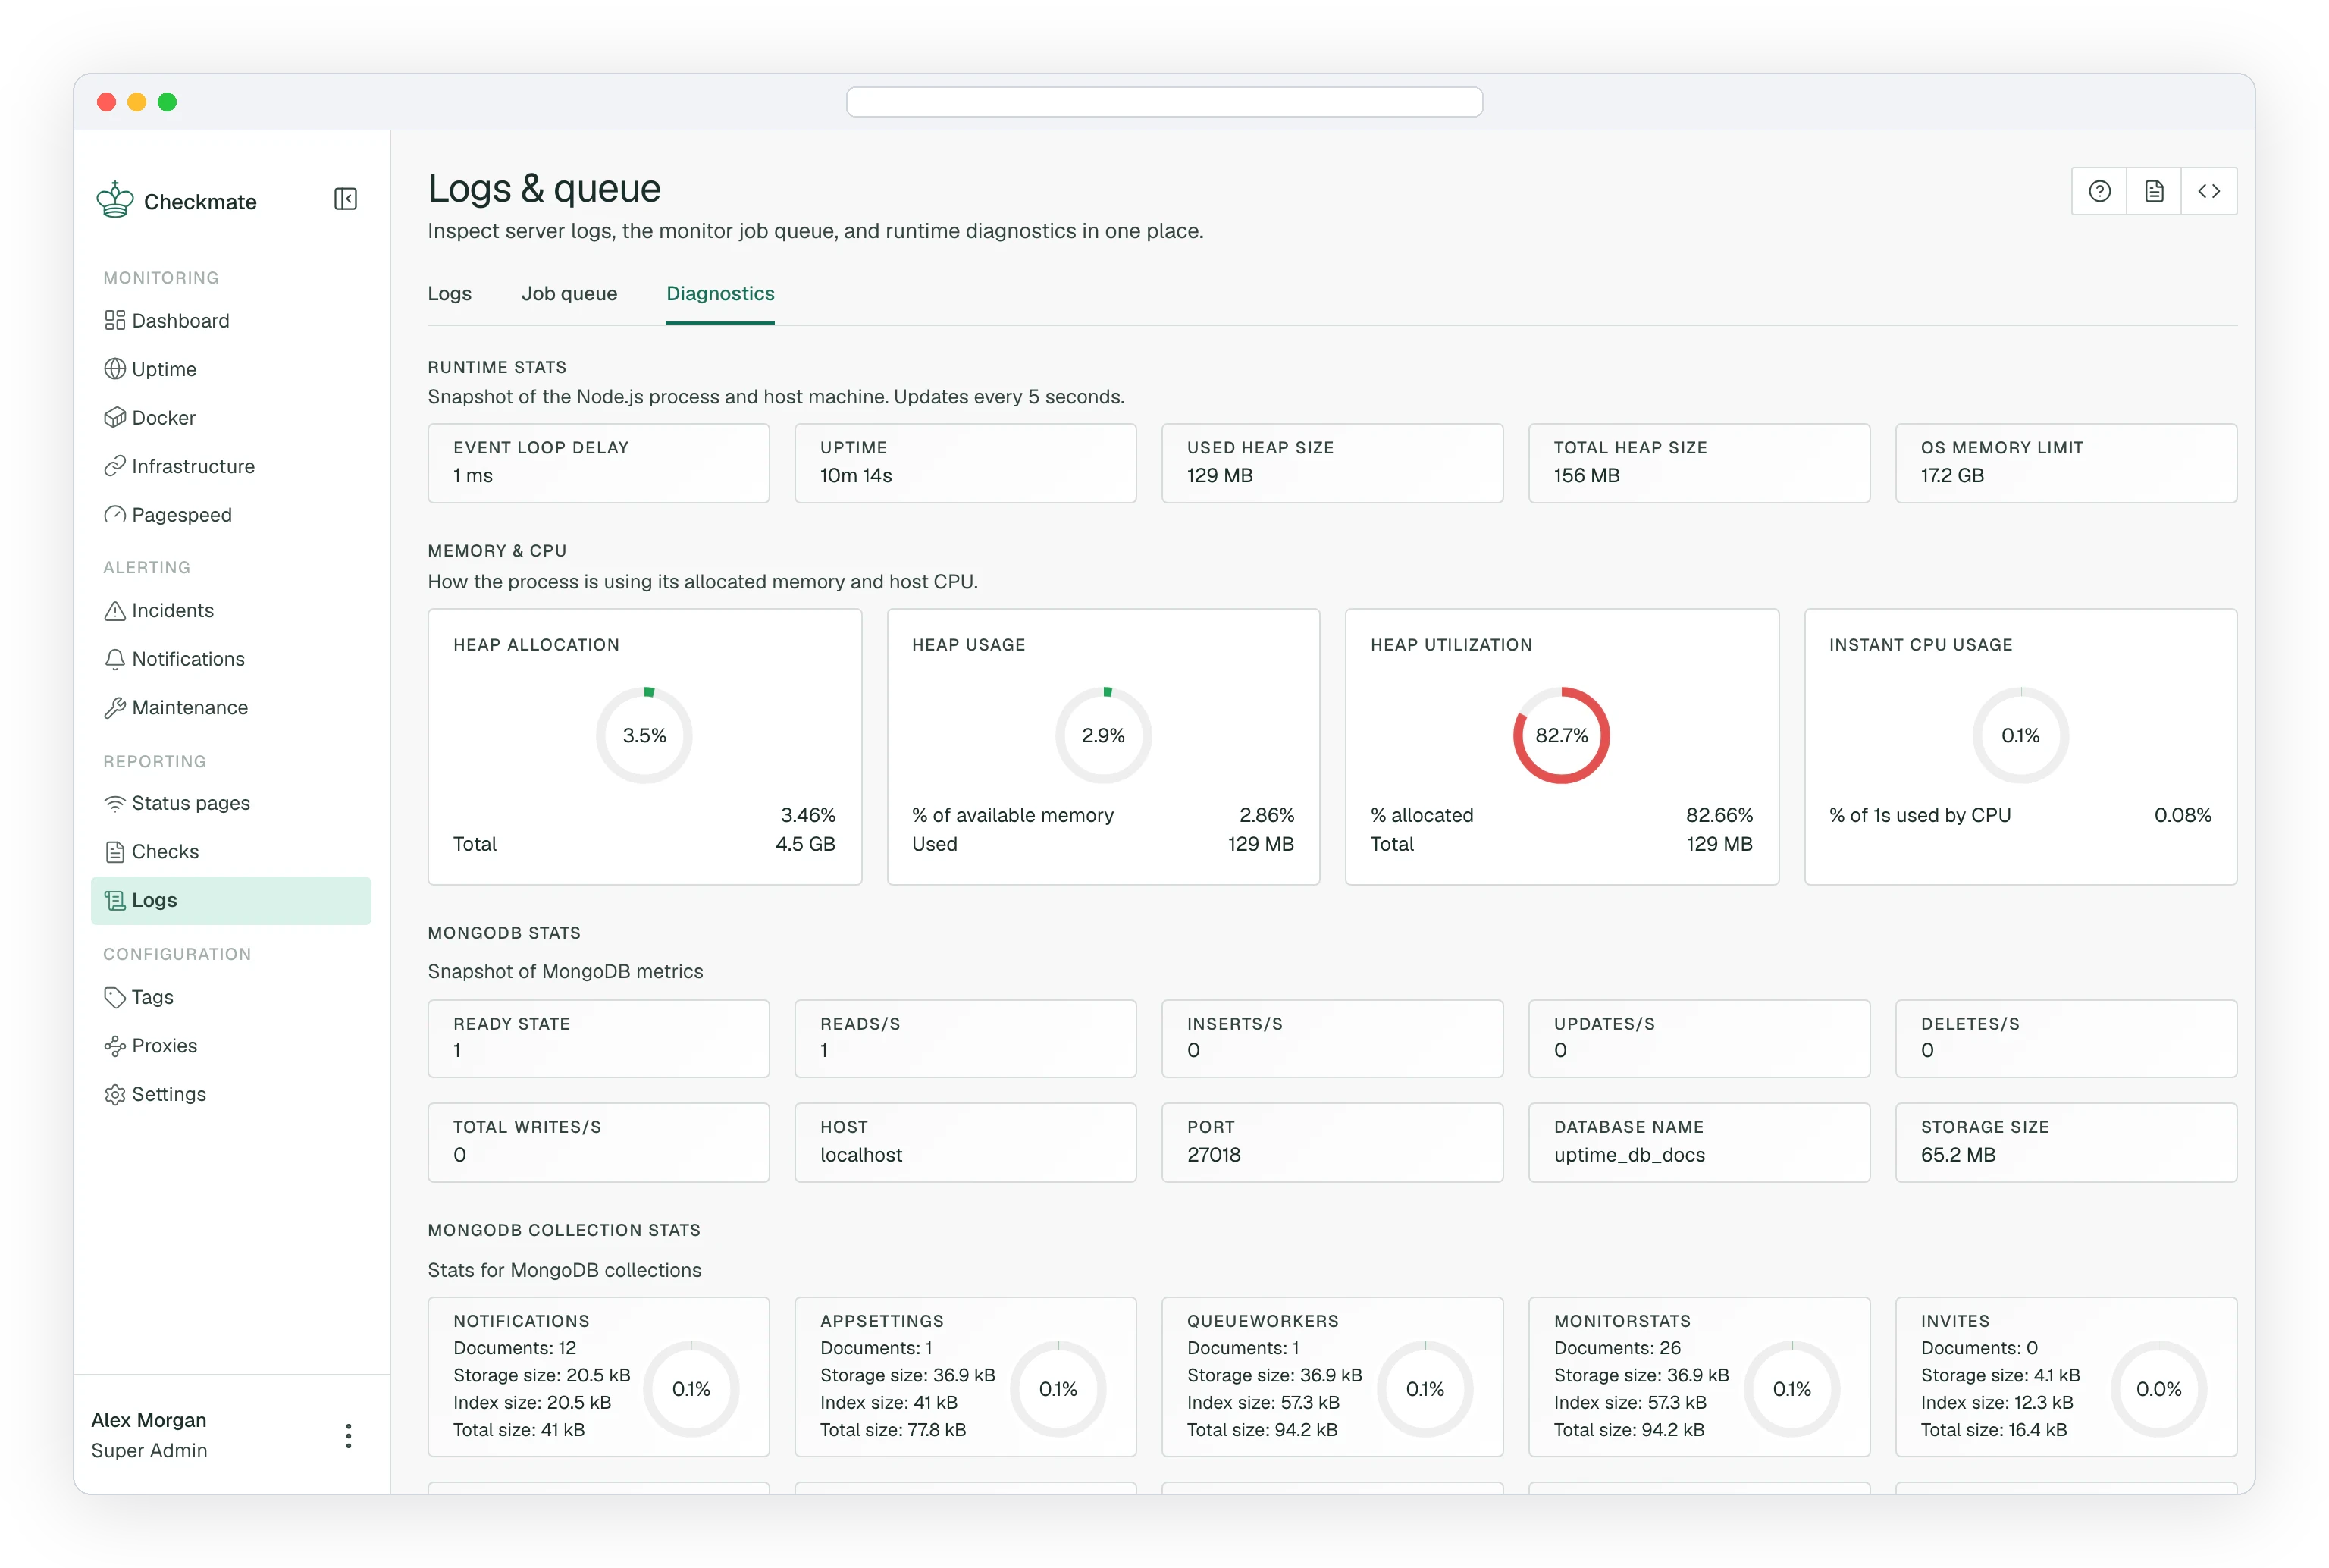
Accessing diagnostics
- Navigate to Logs in the sidebar
- Click the Diagnostics tab
Status overview
The top section shows key status indicators:
- Status: Overall system status (up or error)
- Event loop delay: Node.js event loop latency in milliseconds
- Process uptime: How long the server has been running
- Heap memory: Used and total V8 heap memory
- OS memory limit: System memory available
Performance gauges
Visual gauges display resource utilization:
- Heap allocation: Percentage of heap limit being allocated
- Heap usage: Percentage of allocated heap in use
- Heap utilization: Overall heap usage percentage
- CPU usage: Current CPU utilization
Sustained heap utilization near 100%, or an event loop delay in the hundreds of milliseconds, means the server is struggling to keep up with the checks it has been given. Lengthen check intervals, reduce the number of monitors, or move checks onto distributed workers.
MongoDB stats
A snapshot of the database connection and its throughput. Checkmate writes one row per check, so these rates scale with how many monitors you run and how often they fire.
- Ready state: the Mongoose connection state. 1 means connected; anything else means the server cannot currently reach the database.
- Reads/s, Inserts/s, Updates/s, Deletes/s, Total writes/s: operation rates against the database.
- Host, Port, Database name: where the server is connected.
- Storage size: total size of the database on disk.
MongoDB collection stats
One box per collection, with a gauge showing what share of total database storage it occupies. Each box reports:
- Documents: how many documents the collection holds.
- Bucket count: shown only for time-series collections.
- Storage size, Index size, Total size: disk used by the data, by its indexes, and the two combined.
The checks collection is normally the largest by a wide margin, because every monitor run writes a row to it. If the database is growing faster than you want, that is the collection to look at, and check retention is the setting that bounds it.
Refreshing data
Click the Refresh button to update diagnostics with the latest metrics. The data refreshes automatically every 5 seconds.